 S1CogBench
What System One Decision Models Can and Cannot Do on Cognitive Experiments
arXiv preprint, 2026
Original tasks and scoring. Explicit comparison context. No pooled cognitive score.
Overview
Language models are no longer used only to generate text. Software also asks them for decisions, in routing, guardrails, and automated gates. System One decision models, also called typed decision models, such as Jev, Laya, and Intern-Decision, return one fast decision over the legal options, leaving no text to inspect, and a fast, well-formed decision does not show that the model used the evidence. S1CogBench asks what these models can and cannot do on established cognitive experiments, keeping each task's conditions and scoring apart from disclosed adaptations, and scoring human-response prediction, autonomous execution, and event probabilities separately. It covers five open models and Jev on 24 tasks (27 modes).
- Decision models vary widely in reliability. Laya does not beat uniform choice on 17 of 26 targets, against 3 for Intern-Decision, which also beats the Qwen3.5 backbone it is fine-tuned from on 23.
- Acting well does not imply predicting humans. In Mouselab, Qwen has the highest autonomous reward but predicts humans worse than uniform choice, and Laya has the best NLL of the open models with zero reward.
- Aggregate scores hide condition effects. Horizon, the Wisconsin Card Sorting Test, and reinforcement learning and working memory show how decisions change across conditions that an overall score does not.
- Speed comes mainly from the interface. Under the same readout, Intern-Decision is no faster than its same-size backbone, while generation takes 80 to 316 times as long as one forward pass in the two general models timed.
To our knowledge, it is the first benchmark of System One decision models on established cognitive experiments, and it gives a shared test of whether their decisions respond to evidence, feedback, memory load, and future opportunities before software relies on them.
Leaderboard
Each row is one target, in its own unit. There is no pooled cognitive score and no overall ranking, so compare within a row.
| Domain | Task mode and primary target | Uniform | Full-suite open models | Selected-task APIs | Reference | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Laya | Intern | Llama | Minitaur | Qwen | Jev | Opus | Sonnet | Haiku | Value | Type | ||||
| Loading Table 3… | ||||||||||||||
Bold and gray apply only to the five full-suite open models; gray marks scores not better than Uniform. Opus, Sonnet, and Haiku are Claude 5.5. API cells marked n.e. are outside the measured full-task scope, n.a. lack a full probability score, n.f. have only non-full prefixes, part. retain incomplete records, and canc. were canceled before generation. inv. marks all-invalid reports, which leave the MAE undefined. NLL keeps only the epsilons of primary source scorers, so a zero human-choice probability can give +∞. Temporal discounting reports preference. Domain gives the organizational domain, not a validated ability.
The reference type marks fits to participants' responses (human fit), other participants' responses without a fitted model (human), the analytic solution or answer key (optimal), and policies without human fitting (algorithm). † recovered fit or policy, § same-participant fit, ‡ within-participant holdout, ∗ new reference, ¶ reference added for the remaining rows. ToMi has no human responses, so its reference is the answer key. s Haiku stated option probabilities, a different readout from the open models. Haiku politeness retains one invalid response of 128 and is +∞ on its valid responses.
Table 3 as CSV · The row behind each cell · Results guide · References and Uniform
Every aggregate row
Choose a task from the leaderboard, or below, and a measurement target. Protocols, units, and aggregation stay attached to every result.
Latency records include shared-device execution context and do not establish an isolated model-speed ranking. A task can have coverage across distinct protocol records. Imported files stay in your browser and are marked as user-supplied.
Benchmark
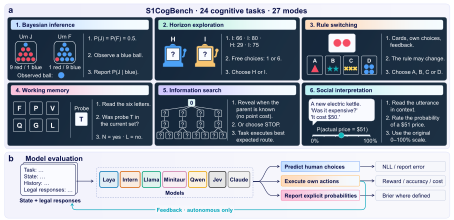
The five open models have at least one accepted full-sample protocol on all 120 task and model pairs. The catalogue retains 31 paradigms in ten organizational domains, and seven are deferred. Coverage does not mean every possible mode or metric.
Tasks
31 source paradigms, their data requirements, and their evaluation entry points. Download the catalogue
Evaluate
One entry point runs each of the 27 modes through its original runner and scorer. The smoke run takes about two minutes on one CPU, with no model weights.
python3.12 -m venv .venv && source .venv/bin/activate
python -m pip install -r requirements.txt
python scripts/fetch_public_sources.py all
python -m s1cogbench doctor
python -m s1cogbench eval --smoke --output runs/smoke
python -m s1cogbench eval --adapter my_agent.py --device cuda:0 --model-label my-model \
--tasks all --output runs/my-model- Psych-101-test is gated. Eight modes stop at
doctoruntil you accept its conditions on Hugging Face and runfetch_public_sources.py psych101. --outputmust be a new directory inside the repository.- Reproducing the CPU validation bit for bit needs Python 3.11. Under Python 3.12, 6 of the 27 modes differ in the last digits of floats.
Build a command for your adapter
The CPU reference policy through this entry point reproduces the CPU validation in all 27 modes. Among neural models, Llama-3.1-8B on a whole A100 is supported. In a pass of 20 calls per mode, all 23 comparable modes match the accepted runs exactly. On a MIG slice of an A100, prompts and identities match but probabilities differ by BF16 rounding steps, so the support does not extend to slices. The other neural models have not run through this entry point. Read the reproduction record
Complete quickstart · Adapter interfaces · Prepare a comparison file
Resources
Evaluation protocols
Visible histories, legal responses, execution rules, and source-specific scoring.
Sources and data access
Original providers, participant splits, versions, and redistribution conditions.
Results guide
Table 3 marks, retained evidence, and how the aggregate files fit together.
References and Uniform
Fit, information, and provenance of every reference, and each Uniform definition.
Reproduction record
What the CPU reference checks and the first real-model pass establish, and what they do not.
CPU validation
Input and scored counts of the 24-task, 27-mode reference check.
Selected-task API extension
Jev and Claude settings, parsers, zero-probability targets, and run records.
API time and cost
Client time and usage-priced cost per target, and the cells not completed.
Supplementary controls
Accepted latency, generated-reasoning, legal-readout, and Claude prefix records.
Controlled latency
Per-mode timings of nine configurations on one A100 at batch size one.
Comparing results
Use the same task, target, mode, protocol, unit, and aggregation.
Task-specific references
Reference fits and algorithms carry their own exposure and provenance. Human-action NLL and autonomous reward are separate comparison targets.
Citation
@misc{hou2026s1cogbench,
  title         = {{S1CogBench}: What System One Decision Models Can and Cannot Do on Cognitive Experiments},
  author        = {Hou, Dengzhe and Yamada, Kazunori D},
  year          = {2026},
  eprint        = {2611.00911},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url           = {https://arxiv.org/abs/2611.00911}
}